Four levels — the Kirkpatrick pyramid
The lens now turns around: after four days of assessing participants, who assesses the training? The framework is the four-level model associated with Donald Kirkpatrick, drawn as a pyramid. Level 1, Reaction: did they respond favourably — the evaluation forms, the smile sheets. Level 2, Learning: did knowledge, skills and attitudes actually move — tests, practical assessments, certification exams. Level 3, Behaviour: are they applying it back on the job — the level where training either becomes work or becomes a pleasant memory. Level 4, Results: did the targeted organisational outcome occur — productivity, quality, sales, safety. The pyramid's shape is the honest part: almost every training programme measures level 1, because forms are easy; each level up gets rarer as it gets more meaningful. The trainer's progressive questions are the whole model in one line: did they like it → did they learn it → did they use it → did it produce results? A good trainer refuses to stop at the first question.
The framework in practice
The framework table turns the pyramid into instructions. Reaction data comes from end-of-course evaluation sheets and class observation — cheap, immediate, and about the experience. Learning data comes from certification exams and the knowledge and performance assessments this whole module has been building — collected before the room empties. Behaviour data has to be fetched from the workplace: performance reviews, supervisor observation, follow-up interviews — someone has to go and look. Results data is the organisation's own numbers: comparing performance before and after, or against a control group, ideally in currency. What the table quietly teaches is that each level belongs to a different moment and a different owner. Reaction belongs to the trainer on the day; learning to the assessor at the end; behaviour to the supervisor weeks later; results to management across quarters. Evaluation is not a form — it is a relay, and most of it happens after the trainer has gone home. Which is exactly why most of it never happens.
Pre-test, post-test and the three-month window
The workhorse instrument for level 2 is the pre-test/post-test pair, and its one iron rule: "soalan mesti sama dengan post-test" — the questions must be the same, or the difference measures your item-writing, not the learning. Same items, before and after; the delta is the effectiveness. It is the same before-and-after logic the 3-2-1 card runs on paper, formalised into data. For levels 3 and 4 the methods are the fetch-it-yourself four: observation — "next week, I go and audit the class" if you trained trainers; survey — structured questions to participants, peers, even customers; focus group — pull a few people from each cohort and listen; interview — one-on-one, where the honest sentences live. And then the question nobody had asked: when? Her answer was specific — within three months. That window is close enough that the change is still attributable to the training; past three-to-six months, "there might be some other factors" — promotions, new systems, staff turnover — and the signal drowns. Evaluation has a shelf life. Do it while the causality is still fresh.
CIRO — the evaluation that starts before the training
The second framework widens the lens: CIRO — Context, Input, Reaction, Outcome — from Peter Warr, Michael Bird and Neil Rackham's 1970 work on evaluating management training. Its distinctive move is that half the evaluation happens before anyone is trained. Context evaluation asks whether the organisation is solving the right problem at all: the training needs, the objectives, the cost-benefit. Input evaluation asks whether the design is right: methods, resources, trainers, duration, budget. Only then come reaction — the participants' immediate response — and outcome: what actually changed, in learning, behaviour and results. Kirkpatrick grades the training after it runs; CIRO also grades the decision to run it. That difference matters most on the trainings that should never have existed — the communication workshop bought to patch a staffing problem, the AI course sold to a team whose actual blocker is data access. On those, level-1-through-4 evaluation reports polite failure after the money is spent; context evaluation would have caught it at the purchase order.
From data to action
All the collected evidence earns nothing until it is analysed, reported and used. The worked example was a youth programme's maths results: a grade distribution (a pie of As through Fs), enrolment growth across semesters, and the money chart — pre- versus post-survey averages by class, every class up, overall average from 56 to 70. Three readings in ten seconds: the programme works, class A leads, class D improved but needs support. That is assessment data doing its actual job — informing the next decision rather than decorating a report. Her reporting rule for our own future submissions: "your report must be integrated enough to make sure all the information is covered — but not so much," which is the entire art of reporting in one breath. Show the distribution, the trend, the delta, the recommendation. Nobody was ever persuaded by the appendix.
Continual, not continuous — the sugar-cane stall
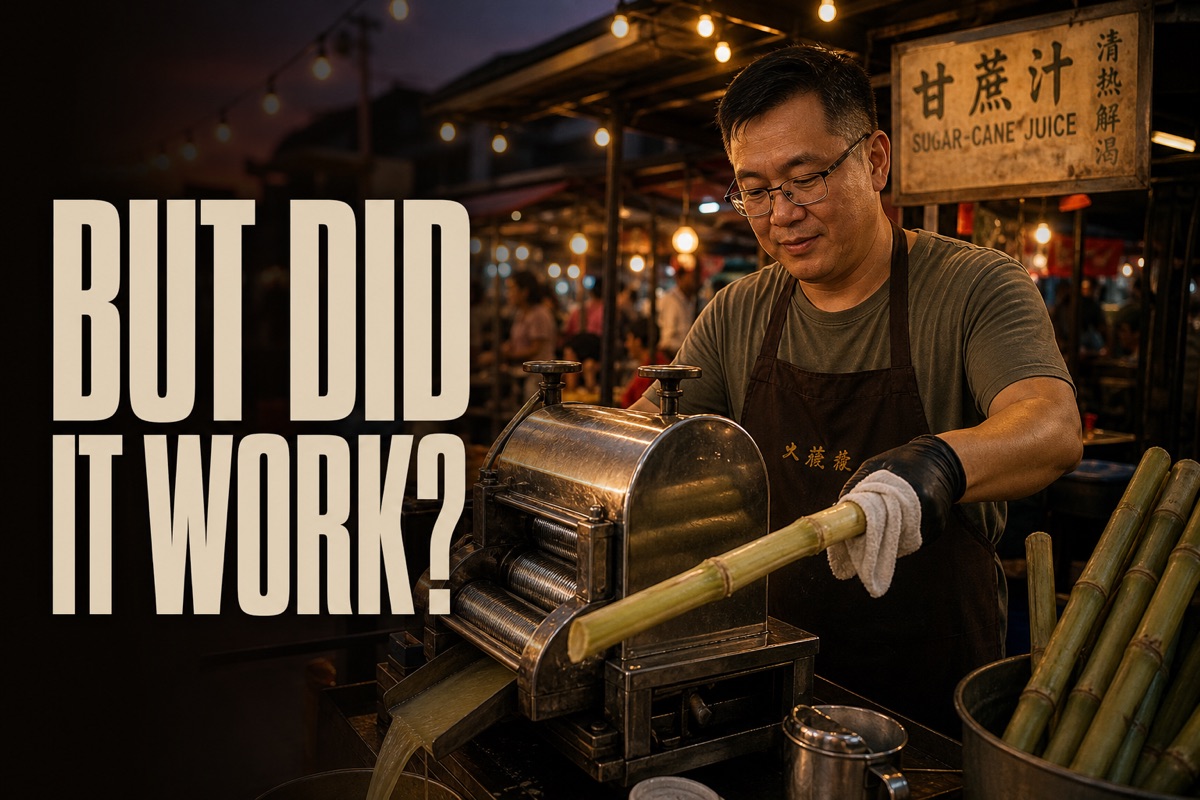
The module closed on the improvement loop, opening with a distinction I had never once made: continuous versus continual. "There is nothing in people development that is continuous — continuous means the gradient is always the same. Impossible." People improve in steps, with flats — and the flats are not failure; "it can be — with reflection." The improvement journey is a staircase, and reflection is the tread between risers. Continual improvement: repeated cycles with pauses, not a smooth ramp nobody has ever actually climbed. The machinery: define your quality standards, establish them, comply with them; then improve through either the linear input–process–output view or the plan–do–check–act cycle. And then the illustration that will outlive every framework in my notes: her favourite sugar-cane juice stall. The vendor wraps every cane in muslin cloth and hangs them on the fence so they never touch the ground; the press gleams; the counter is clean. "When you look at the stall, your conscience is clear — and the quality is all consistent, because she has a very dedicated process." Quality of input, quality of process, quality of output — an entire operations course hanging on a fence in cloth wrappers. Her closing charge: "do it right, and right the first time. Start from the very beginning — start from now."
Case Study
evaluating the DJC AI course on all four levels
My DJC AI course has been evaluated at level 1 since it began — happy sheets, warm words — and I have been quoting those forms as proof the course works, which today exposed as answering "did they like it?" and reporting it as "did it pay?". The honest rebuild, level by level. Level 1 stays but shrinks: three yes/no questions plus one free-text line, per the Likert lesson. Level 2 becomes a pre/post pair with identical items — five practical tasks (draft this email with AI, extract this table, check this claim) attempted cold on day one, re-attempted at course end; the delta is my effectiveness, in the participant's own artefacts. Level 3 is the three-month window, taken literally: a calendar entry per cohort at week ten — inside the window, before promotions and reorgs blur the signal — with one question by WhatsApp: "show me the last thing you used AI for at work." A screenshot is behaviour evidence; a long silence is too. Level 4, for corporate cohorts, is negotiated at booking: the client names the number the course should move — hours on report-writing, first-draft turnaround — and we compare before and after. Scary, and exactly the level a premium course should be selling. The CIRO context check I am adopting as a sales-call script: what problem is this training solving, and is training the fix? One recent corporate booking wanted AI training for a team whose real blocker was that their data lives in seventeen spreadsheets nobody owns — context evaluation would have sold them a smaller course and a better outcome. And Mana Mana gets the sugar-cane standard: our training quality should be visible the way muslin-wrapped canes are — SOPs printed and clean, assessment sheets filed, records current — so that anyone who looks at the operation sees the dedicated process, and the conscience is clear.
Reflections
The four levels are really a ladder of courage. Level 1 risks nothing — bad feedback bruises. Level 2 risks the session — maybe they learned little. Level 3 risks the design — maybe it never transferred. Level 4 risks the business case — maybe the training should not exist. Every level up asks the trainer to gamble something realer, which is exactly why the industry lives at level 1. The week's arc points one way: a professional is someone who volunteers for the higher levels. And continual-not-continuous is the kindest true thing anyone has said about improvement all week. Day 1's forgetting curve said decay is the default; today's staircase says growth comes in steps with flats, and the flats are where reflection lives. This journal is the flat between risers. Tomorrow is the assessment — the fifteen minutes the whole week has been aimed at — and it seems fitting that the last full day of content ended with a sugar-cane vendor whose process is so clean her evidence hangs on the fence in plain sight.